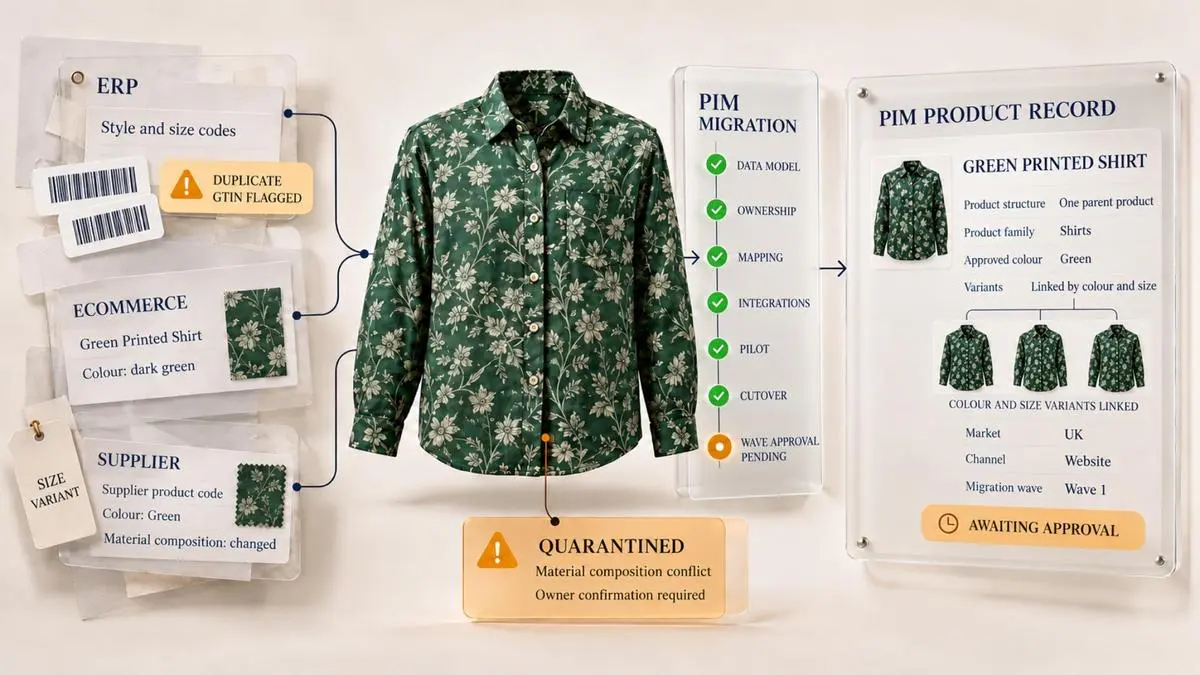
A retailer may have the same product recorded differently across systems. Consider a green printed shirt: the enterprise resource planning (ERP) system uses a code to manage stock, the ecommerce platform uses a different code to manage online listings, and the supplier identifies the shirt with a third.
Each system records information for a different purpose, and a change made in one can stay in that system. For example, if the supplier changes the shirt's material composition, the ecommerce platform keeps showing the original until someone edits the listing by hand. The ERP gives each size its own code, so a single shirt is stored as one item per size.
When these records are imported into a new Product Information Management (PIM) system, the import can run to completion even though the records still disagree. The retailer could end up with duplicate products, unlinked size variants and conflicting material descriptions.
A PIM implementation checklist helps retailers identify these issues before migration. It gives the team a structured way to review existing product information, resolve inconsistencies and decide how records from different systems should be organised in the new PIM.
This article covers the stages of PIM implementation, from defining the product data model and assigning ownership of individual fields to cleaning records, planning the migration and testing the results.
What are the stages of a PIM implementation?
The PIM implementation process has nine stages: defining the scope, inventorying source systems, designing the data model, assigning field ownership, cleaning and mapping the data, setting up integrations, running a pilot, testing and rehearsing the cutover, and migrating in waves under ongoing governance.
Each stage should have a clear, documented outcome that the team can use to guide the next stage. The product data model and field ownership must be agreed before cleaning and mapping begin, because these decisions determine how the data should be structured and which issues need to be corrected.
Stage | Main work | Exit evidence |
Define Scope | Agree what the project should achieve and which products, markets and channels move first. List anything that stays out. | Approved scope and success measures |
Inventory sources | List every place product data is created, stored or used, including systems, supplier files and spreadsheets. | A list of sources and what depends on each |
Design the data model | Decide how a product is described in the new PIM: its identity, sizes and colours, categories, attributes and the rules a record must meet. | An approved data model and a description of each field |
Assign ownership | Decide which system holds the correct value for each important field, and who owns, edits and approves it. Name who settles a disagreement between systems. | A list of field owners and the approval steps |
Clean and map | Find the errors in the current data, decide how to fix each type and write rules that move each old field into the new model. | A data quality report, a log of issues and a field mapping document |
Configure integrations | Set up the connections that send product data into and out of the PIM, along with approval steps and monitoring. | Tested connections between systems |
Run a pilot | Load representative and difficult products, then revise the model, rules or mapping where they fall short | A pilot report with each issue assigned to an owner |
Test and rehearse cutover | Check that migrated records match the source, test everyday workflows, time the final data load and practise recovering if something fails. | Signed-off test results and a cutover plan |
Migrate in waves and govern | Move products in planned groups, monitor errors, train the owners and stop edits in the old systems at the agreed point. | Sign-off for each group of products, post-launch monitoring results and an agreed review routine |
The stages often overlap, and a pilot can send the team back to the data model or the cleaning rules. The sequence is a practical framework based on common implementation practice. The time each stage takes depends on how clean the catalogue is, how many systems connect to the PIM and how quickly owners make decisions.
Build the PIM data model before mapping legacy fields
The PIM data model describes how product information will be structured after migration. If legacy fields are mapped first, the old system's unclear columns shape the new platform. Building the model first lets the mapping move each old field into a structure the team has already agreed.
The model should define:
how a product, style, variant, pack and bundle are described and how they relate to each other
the identifiers each record keeps, including old codes
the category structure and product families
every attribute, with its meaning, data type, unit and allowed values
which values apply everywhere and which vary by market, channel or language
the stages a record passes through, from draft to published
the fields a record needs before it can be published, for each family and destination
Different products need different information depending on their category and where they are sold. Each category therefore needs its own list of mandatory fields. GS1’s Global Data Model addresses this by grouping product information into four levels: core attributes required globally, category-specific attributes, regional requirements and local requirements, including those set by national regulations. Akeneo uses a similar approach in its PIM, where required fields are set by product family and completeness is checked for each language, region and sales channel.
Using the green printed shirt example, the model would look like this:
The ERP supplies the stable style and size codes.
The PIM holds the shirt as one parent product, with each colour and size as a variant beneath it.
Colour becomes a value chosen from an approved list, so “Green”, “dark green” and “GRN” become one value.
Material composition and care instructions are stored in separate fields.
The UK description is stored for the UK market and leaves the global technical record unchanged.
Images attach to the correct colour and stay managed in the digital asset management system (DAM) if it holds the originals.
How should retailers choose which system owns each product field?
Retailers should name one system as the authority for each important product field, meaning the system whose value is used when systems show different details. The choice depends on where the information comes from, who checks and approves it, and how often it changes. For example, the PIM can manage product descriptions, while the ERP manages prices and stock levels.
Four questions help decide the owner of each field:
Where is the value created? The supplier provides the material composition, the merchandising team writes the description and the finance team sets the price.
Which system can check and approve it best? A PIM can apply required-field and format rules to a description before it is published, and the ERP can check stock against warehouse movements.
How often does it change? Stock and promotional prices can change many times a day, while composition and care instructions change rarely.
Which systems use it? When several channels use a value, one owning system sends it to the others, so every channel shows the same information.
The table below gives an example of how product information can be divided across systems. Retailers can adjust it depending on the systems they use and where their product information comes from.
Product information | System responsible | Role of the PIM |
Style, colour and size codes | ERP | Uses these codes to link sizes and colours to the correct product |
Product title and description | PIM | Stores and publishes approved product descriptions |
Material composition and care instructions | PIM, based on supplier information | Maintains the approved details and sends updates to sales channels |
Product images | DAM | Connects the correct images to each product and colour |
GTIN | ERP or PIM | Records the GTIN for each variant and checks for duplicates |
Channel-specific titles and attributes | PIM | Holds the product information required by each sales channel |
Price | ERP or pricing system | Receives pricing information when needed for product listings |
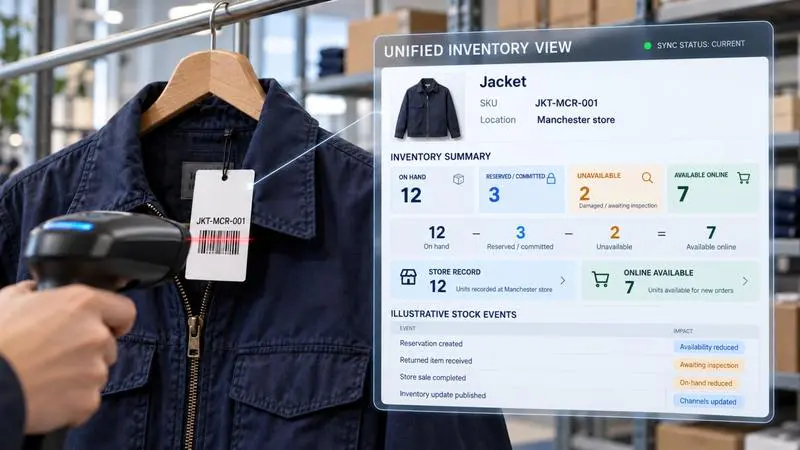
Stock levels | ERP or warehouse system | Uses stock information provided by the inventory system |
In the green printed shirt example, a retailer may use its ERP to manage the style and size codes, the PIM to maintain the description and the DAM to store product images. The supplier provides details such as material composition and care instructions.
If the supplier changes the material composition, the retailer can update the approved information in the PIM and send the revised details to all connected sales channels. This keeps product information consistent across every listing from a single update.
Retailers should also maintain a field ownership register that records which system is responsible for each field, who approves changes and which other systems receive the information. It should also specify which source takes priority when records contain conflicting values.
The register can be used throughout implementation, particularly when mapping fields from existing systems and testing the migrated data. After launch, it provides a reference for managing product information and approving future changes.
What product data should be cleaned before migration?
Before migration, retailers should clean the product data that affects how products are identified, grouped and described. This includes duplicate records, product identifiers such as GTINs, size and colour variants, attribute values, units of measure and missing mandatory fields. Each issue then receives one of five treatments, depending on when and where it is best resolved.
The five treatments are:
Fix before migration: used when the correct value is known and the source system can be edited. For example, a duplicate shirt record is merged and a mistyped GTIN is corrected.
Transform during migration: used when a rule can produce the correct value for many records at once. For example, “GRN”, “dark green” and “Green” all load as the approved value “Green”.
Enrich after migration: used when a value is missing but the product can go live without it. For example, longer marketing descriptions are added in the PIM once the first wave is live.
Exclude or archive: used when a product is no longer sold and has no future use. For example, a shirt from a discontinued season stays in the old system.
Quarantine: used when a record needs a decision from its owner before it can be loaded. For example, a shirt with two different material compositions is held until the supplier confirms the correct one.
Retailers should check GTINs carefully, because each size and colour variant needs its own number. GS1’s GTIN Management Standard (Release 1.1, September 2023) explains when a product needs a new GTIN, and local regulations take precedence where they differ. Before migration, the team should confirm that every variant has a GTIN and that each GTIN is assigned to only one variant.
For every issue, the team should record the treatment chosen and who approved it. The field ownership register shows who makes each decision. After migration, the record of treatments is us
Migrate product data in waves
Moving an entire product catalogue into a new PIM at once can make errors difficult to identify and correct. A more manageable approach is to migrate the data in smaller waves, checking the results before moving on to the next.
The first wave could cover a single product category and sales channel, such as shirts listed on the retailer’s website. It should include different sizes, colours and product attributes so the team can check whether the new PIM handles them correctly. Starting with a smaller wave also makes it easier to identify problems with the data structure or cleaning rules before migrating the rest of the catalogue.
Each wave should go through the following checks:
Check record counts: Compare the number of records in the original system with those imported into the PIM. Any records that were excluded, rejected or set aside for correction should be accounted for.
Check the imported information: Compare a sample of records with the original data to confirm that details such as material composition, pricing and images have been transferred correctly. The teams responsible for these fields should review the results.
Test the migration: Run the import in a test environment before moving the data into the live PIM. This helps the team identify errors, estimate how long the process will take and make any necessary corrections.
Prepare a recovery plan: Decide how the retailer will restore its previous product listings if the checks fail during the migration. The team should also agree who has the authority to stop the process or approve a rollback.
Get approval before continuing: The people responsible for the relevant product information should review and approve the results before the next wave is migrated.
Once the first wave has been checked and approved, the retailer can move on to other product categories, sales channels and integrations. Any errors found during an earlier wave should be corrected in the data cleaning rules or field mappings before the next import begins.
How is a PIM implementation tested?
A PIM implementation is tested in layers: the migrated data, the validation rules, the integrations with other systems, the output to sales channels and the workflows people use. The team agrees to pass criteria for each layer before testing starts, and any critical failure is fixed before go-live.
The six layers are:
Migrated data: record counts and field values match the source. For example, every source record has one recorded outcome, and sampled shirts show the correct composition and price.
Validation rules: required fields, formats and approved values work as set. For example, a shirt with an empty care instruction field is flagged as incomplete for the UK website.
Integrations: data moves correctly between the PIM and connected systems. For example, a new size code created in the ERP appears as a variant of the correct shirt in the PIM.
Channel output: listings show the approved information. For example, the UK website displays the approved composition, and the images match the colour.
Workflows and permissions: people can complete their tasks. For example, a merchandiser edits a description, and only an approver can publish it.
Cutover rehearsal: the full load runs in the planned time. For example, the rehearsal finishes within the agreed window, and the rollback steps restore the previous listings.
During testing, the team should record each defect and rate it as critical or minor. Critical defects include a wrong price, a wrong material composition or a size variant linked to the wrong product, and the team should fix and retest these before go-live. Minor defects, such as small formatting differences, can be fixed after launch if the field owner agrees. Before go-live, the owner of each field named in the register should approve the test results for that field.
PIM implementation checklist
The checklist below follows the nine stages of the implementation. Each row states what the team should do and the evidence that shows the stage is complete.
Stage | Checklist item | Evidence of completion |
Define the scope | Agree the categories, channels, markets and success measures for the first wave | Written scope approved by the project owner |
List source items | Identify every system that holds product data and who maintains it | System inventory with a named owner for each |
Design the data model | Define product families, variants, mandatory fields for each channel and market, and approved values | Data model approved by the merchandising and ecommerce teams |
Assign field ownership | Name one authority system and one approver for each important field | Completed field ownership register |
Clean and map the data | Apply the five treatments and map legacy fields to PIM fields | Treatment record and mapping sheet, with GTIN checks complete |
Set up integrations | Connect the ERP, DAM and sales channels according to the field ownership register | Test records move between systems as the register specifies |
Run a pilot | Load the first category and channel | Pilot findings logged and cleaning rules updated |
Test and rehearse cutover | Test the six layers, rehearse the full load and agree the rollback plan | Critical defects closed and field owners’ approval recorded |
Migrate in waves | Load each wave, reconcile record counts and obtain approval before starting the next | Reconciliation report and approval for each wave |
Manage product data after PIM goes live
Product information needs regular attention after the PIM is implemented. Suppliers may change product specifications, new products are added to the catalogue, and marketplaces may introduce new requirements. Retailers need a process for managing these updates so that the information remains accurate across all sales channels.
The field ownership register created during implementation supports this work, and PIM governance covers four areas:
Approving changes: updates to important product fields should be reviewed by the person responsible for that information before they are published.
Checking completeness: teams should regularly check that products have all the information required for each market and sales channel, and assign any missing details to the relevant team.
Reviewing data accuracy: teams should compare a sample of live product listings with the information held in the PIM and other source systems, then investigate and correct any differences.
Managing new requirements: when new product categories, attributes or sales channels are introduced, teams should review how the information will be managed and update the field ownership register.
Complete and consistent product data also supports newer discovery channels. Retailers who want to prepare their catalogue for AI shopping tools can read how to prepare product data for AI discovery in ChatGPT Shopping.
How Fynd AI PIM supports PIM implementation
Fynd AI PIM helps retailers manage product information during implementation and after launch. Retailers can define product attributes, create templates and set up product relationships. The platform also includes validation rules that identify missing or incorrect information before it is published.
Once the existing product data has been migrated and checked, Fynd AI PIM can help teams complete product listings by generating titles, descriptions and SEO keywords from product images or existing data.
The platform also provides approval workflows, task assignments and role-based access for vendors, agencies and internal teams. Retailers can decide who is responsible for updating, reviewing and approving different types of product information.
For publishing, Fynd AI PIM provides ready-to-use marketplace schemas, channel mapping and indicators that show whether the required product information is complete. Retailers can publish product information across sales channels, while APIs and sync logs help teams track updates and identify issues.
Consider the green printed shirt example discussed earlier. Once the data model is in place, the shirt can be listed as one parent product with its colour and size variants linked to it. The supplier’s approved material composition is stored in the PIM, and a change to it reaches the connected sales channels from a single edit.
Before moving the first wave of products into the live PIM, retailers should test these processes using actual catalogue data. This includes checking product relationships, field validations, approval workflows and whether updates reach the intended channels correctly. The team should also confirm that every critical value on the shirt can be traced to its owner.
Want to see how this would work for your product catalogue? Fynd AI PIM helps teams organise product information, manage updates and publish accurate listings across sales channels
Explore Fynd AI PIM